 GitHub
The problem
AI chatbots can be slow, and each question sent to them costs money. In real life people keep asking the same things in different words for example:
- "How do I bake a chocolate cake?"
- "What's the process for baking a chocolate cake?"
A normal system treats these as two separate questions, so it pays the AI twice and waits twice for what is really the same answer.
This project sits in front of the AI and acts as a memory with good judgement.
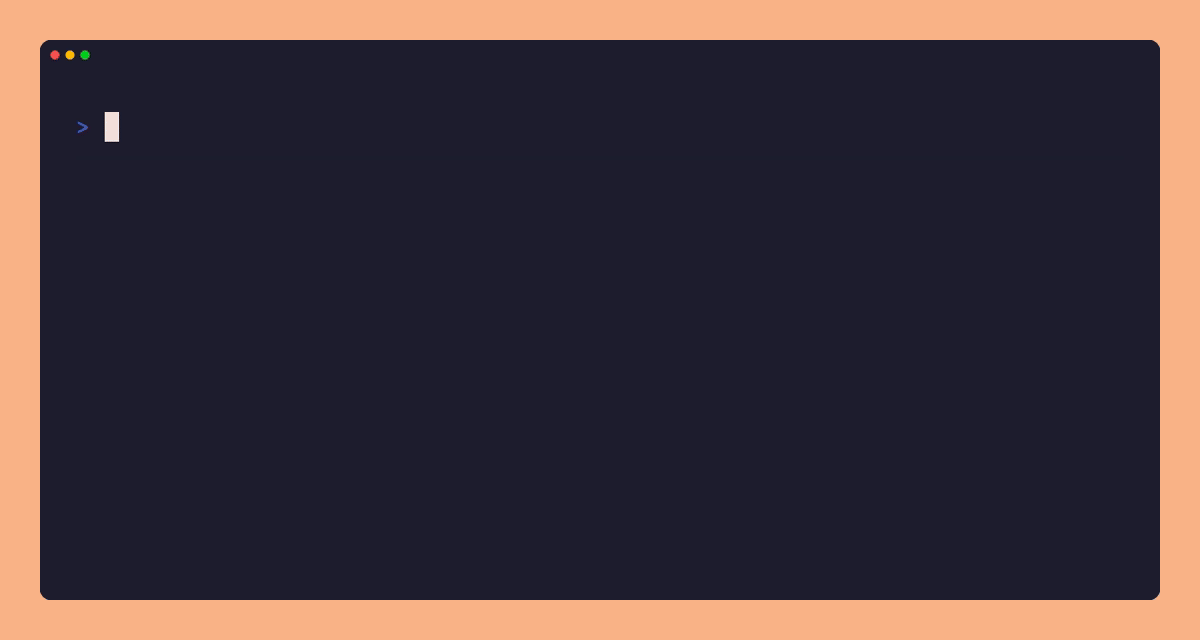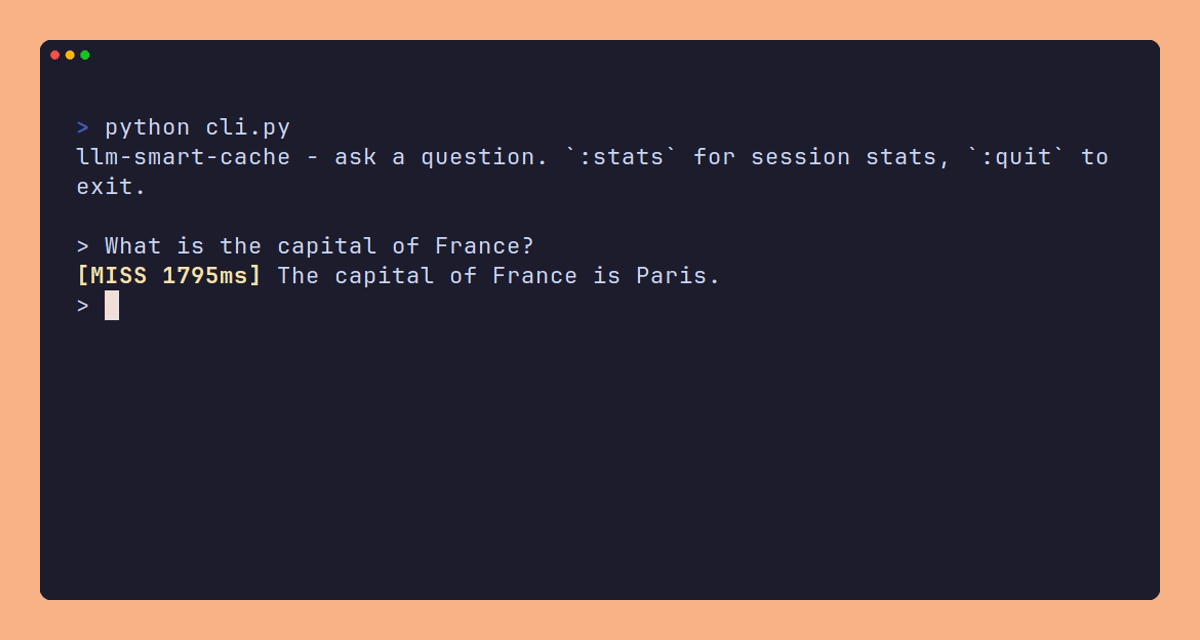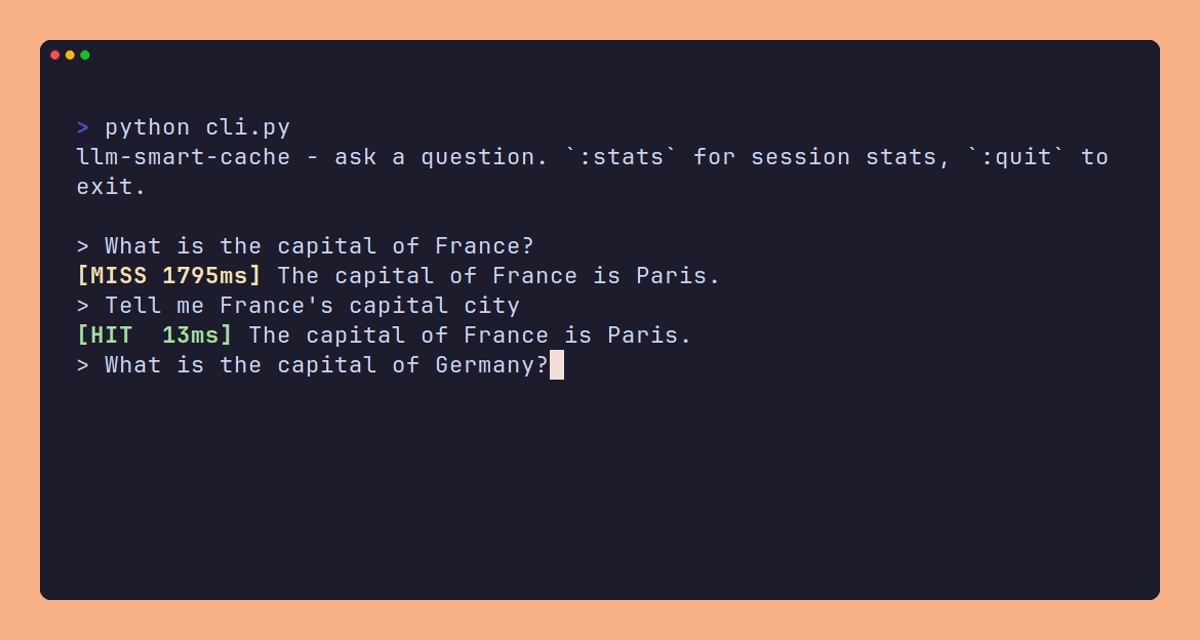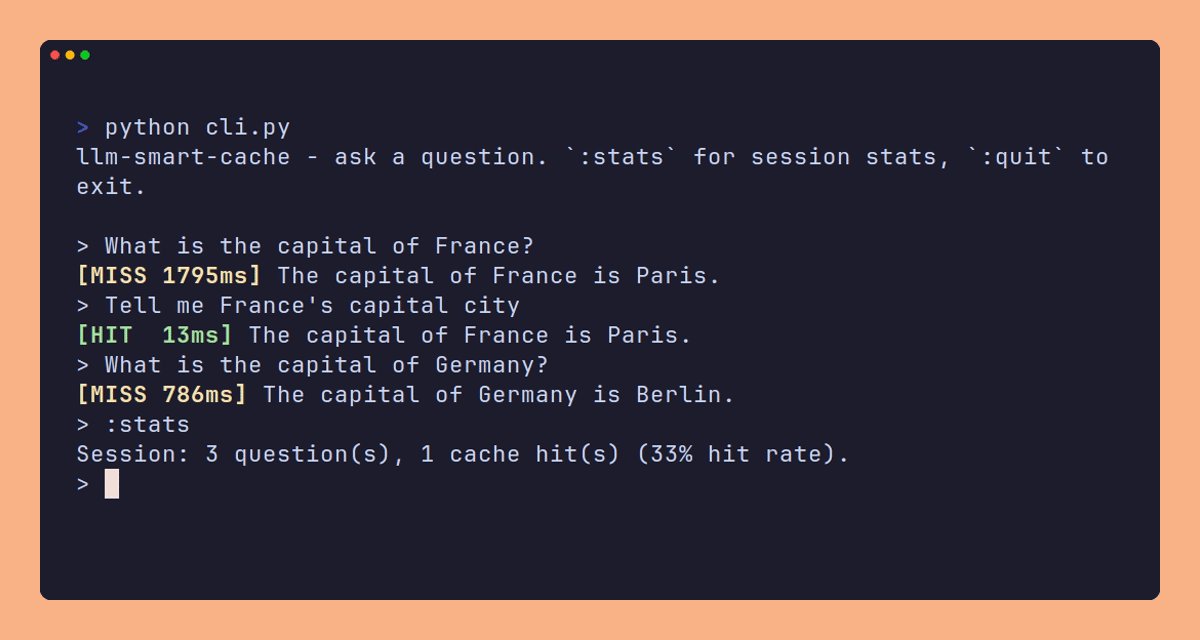
- When a question comes in, it checks whether it has already answered something that means the same thing, even if the wording is different.
- If it has, it returns the saved answer right away. That takes about 9 milliseconds instead of about 800, and it costs nothing.
- If it hasn't, it asks the AI, gives you the answer, and saves it for next time.
Why?
Faster, Cheaper, Smarter than basic cache (matches on meaning, not by words)
Tech Stack
- Python: Core programming language
- sentence-transformers: Turns text into numbers (embeddings) that capture its meaning
- FAISS (by Meta): Searches those embeddings for the closest matches
- pytest: Automated tests for each core part
Architecture
question ─▶ Embedder ─▶ VectorDB.search (FAISS, top search_k neighbors,
                              │         TTL-expired ones skipped)
                              │
          any neighbor with distance < CACHE_MAX_DISTANCE?
                    │                    │
                   yes                  no
                    │                    │
              return the closest     call the LLM (OpenRouter),
              one's cached answer,   cache the new answer,
              no LLM call            return it
The question gets passes to the embedder to get the semantic meaning and converts it to vectors. Then those vectors get stored in VectorDB (which uses FAISS to search up top 5 nearest neighbours). If the nearest neighbour is near to the CACHE_MAX_DISTANCE, then it returns that answer, else it will call the LLM to generate the answer and return. Then that answer gets stored.
To Do
Benchmark Improve Benchmark
Improve Model Testing Currently this smart cache only uses one model. Maybe we can try other models so that it is much more better to benchmark the smart cache
Package Easily deployable and usable with package
Context Cache This would check to see if the context first of the cache. It is possible similar questions are asked in different contexts